Reliable Context
Articles (English) - Page 1 / 7
Federated Query Completeness in Knowledge Graphs: A Certificate
How to decide whether a federated SPARQL result is complete, incomplete or unknown: Darari et al. completeness statements, a query-level certificate, six failure tests and an 85% recall worked example, 2026.
Conflicting Sources Fact Checking: What Explanations Must Show
A 2026 explainer on conflicting sources in fact checking: evidence-relation matrix, span removal tests and six scores, drawing on CLUE, ConfRAG (57.2% of 1,814 questions) and NatConfQA.
Knowledge Graph Edge Citation Verification: A Span Test
How to verify a knowledge graph edge against its cited source span: a 2026 acceptance test with seven adversarial cases, four verdicts, support-rate arithmetic with Wilson intervals, and the literature behind each step.
Semantic Entropy Hallucination Detection: An Evidence Audit
Evidence audit of semantic entropy hallucination detection in 2026: what Nature, EACL and 2026 preprint results measure, why single-cluster answers escape, and a paired source-support audit design.
AI Tool Output Verification: Did It Establish a Fact?
A 2026 guide to AI tool output verification: distinguish successful calls from supported facts, classify incomplete observations, and evaluate claims with independent fixtures and provenance.
JSON Evidence Binding Test: Right Value, Right Record?
A 2026 protocol for a JSON evidence binding test: frozen manifest, per-record ledger, RFC 6901 pointer fixtures, matched order and path conditions, and when deterministic assembly beats LLM nesting.
Scientific Claim Verification With Figures: A Visual Audit
How to test scientific claim verification with figures and tables: SciFact, SciVer and SciClaimEval compared, a paired synthetic fixture, Wilson intervals and a 2026 evidence ledger.
Agent Memory Admission Control: Can It Trust Its Own Guess?
A 2026 admission test for agent memory: matched fixtures, false-admission and valid-admission rates, and HaluMem's paper-reported false memory resistance (44.94% to 80.78% on Medium).
Structured Data Verification: When Facts Need a Query
Structured data verification for claims over joined tables: ClaimDB's 53,368 claims, a synthetic SQLite witness with 11 perturbations, separate abstention and reproducibility metrics with Wilson intervals (2026).
OWL import closure: Can an old graph be reinterpreted?
A 2026 analysis of OWL import closure and historical graph replay, with a two-hop dependency manifest, an entailment comparison, and criteria for version pinning or declaring reconstruction unknown.
Negation in Information Retrieval: Recall vs. Violations
A 2026 research report on negation in information retrieval: NevIR and ExcluIR evidence, recall versus exclusion metrics, and a reproducible collection-level release protocol for retrievers and rerankers.
Knowledge graph fact verification: a controlled evidence test
A 2026 research report on knowledge graph fact verification, comparing FactKG studies and specifying paired edge-removal controls, evidence audits, calibration, abstention and reproducible graph snapshots.
Wikidata Statements, References, Ranks and Qualifiers
How Wikidata lets conflicting claims coexist: statements, snaks, qualifiers, references and ranks, a real example in JSON and RDF, and enterprise lessons.
W3C PROV Explained: Entities, Activities and Agents
A worked introduction to W3C PROV: the three core types, the core relations, one value traced in PROV-N and PROV-O, and what PROV validity does not prove.
SEC Rule 17a-4: WORM and the Audit-Trail Alternative
How SEC Rule 17a-4(f) lets broker-dealers keep electronic records in WORM form or with a complete time-stamped audit trail, and what each path requires.
Survivorship Rules for Golden Records: Worked Examples
Recency, source priority, completeness and majority vote applied to one fictional supplier record from four sources: what each rule keeps and loses.
Tamper-Evident Logs: Hash Chains, Merkle Trees, CT
How hash chains, Merkle trees and transparency logs make edits to a log detectable, with computed examples, and what integrity proofs cannot tell you.
Why Language Models Hallucinate: Incentives and Abstention
Why LLMs hallucinate: the singleton-rate bound, how accuracy-only grading rewards guessing, where RAG fails, and why unknown must be an allowed answer.
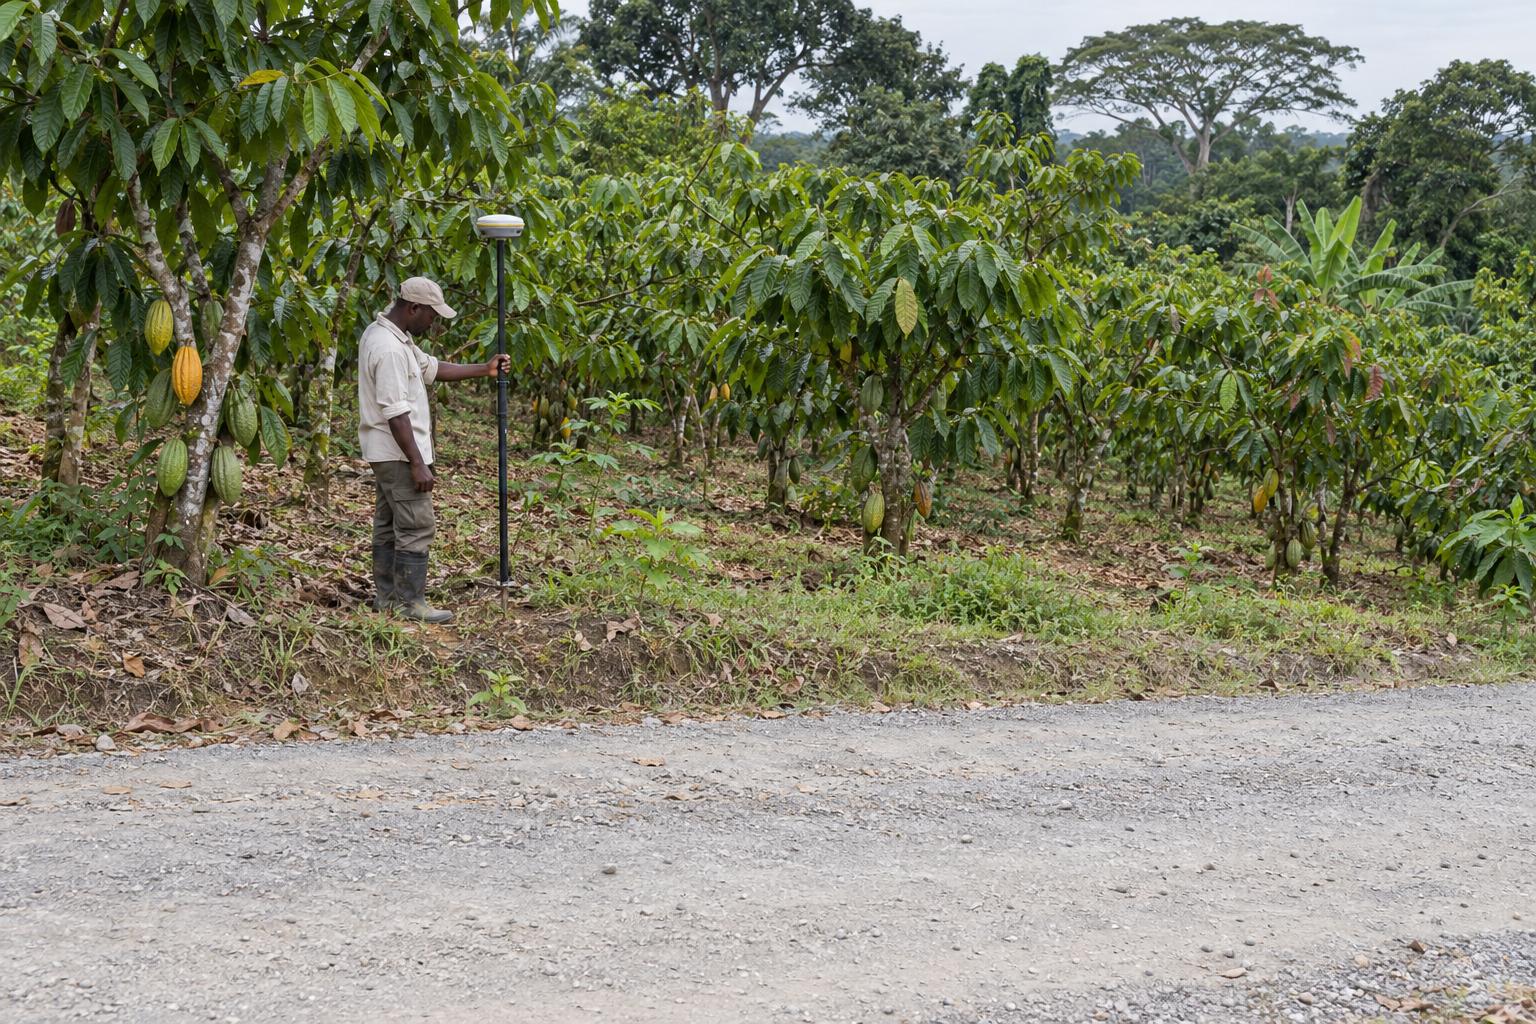
Traceability Evidence: GS1 EPCIS, DSCSA and the EUDR
Three traceability regimes compared by the question each asks of a record: GS1 EPCIS events, US DSCSA package-level tracing, and EUDR due diligence data.
SQL:2011 Temporal Tables in Practice
System-versioned and application-time tables in SQL Server, MariaDB and PostgreSQL: DDL, AS OF queries, retention, and what history does not record.
Sanctions Screening as Entity Resolution: OFAC 50% Rule
Sanctions screening splits into name matching, identity and ownership aggregation. A worked example of the OFAC 50 Percent Rule and the EU approach.